Regression Testing LLM-Driven Applications
How we make sure Coach doesn’t break every time we update a prompt or an LLM provider releases a better or faster or cheaper model that we want to try out.
Author: Olutosin Sonuyi, Director of Engineering at CareerVillage.org
Software engineering has benefitted from decades of well-established processes for testing applications, but many of those processes fail for applications in which LLMs drive a large portion of functionality. In this article, we’ll take a high-level look at how CareerVillage.org’s AI-powered career coaching platform, called Coach, is built, and share some of the methods that worked well for us as we built a testing framework for maintaining high-quality outputs as our application evolved.
Why we care
For as long as we’ve been building Coach, large language models have been a major component at the core of our application’s functionality. In the most direct case, LLMs power the conversations that learners have with Coach as they explore different careers, get advice, learn how to give feedback, etc. Outside of learner conversations, we also use LLMs to generate insights for our advisors, to suggest career path goals, and to provide proactive encouragement to our learners off-platform.
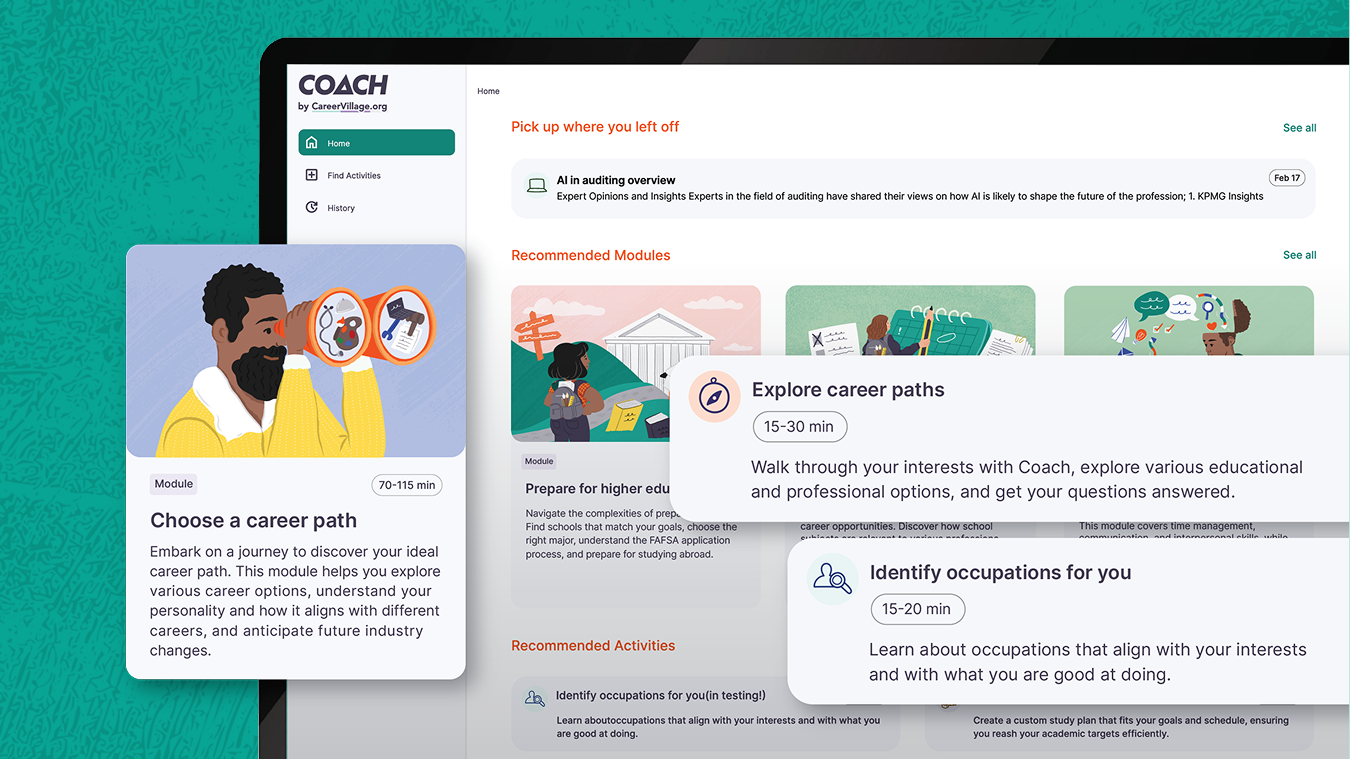
LLMs are particularly suited for conversational interfaces: they adapt to user requests, offer natural variation from run to run, and can be prompted into new operational regimes without costly code changes. In addition to this inherent flexibility, every reputable service provider, from OpenAI to Anthropic, releases new models multiple times a year, often with bespoke variants optimized for latency, performance, or specific tasks. Lastly, since most of the major providers have converged on a largely standardized output format switching models across providers often requires minimal investment.
However, the flipside of this wonderfully exciting flexibility and fast-moving technological landscape is that leveraging these benefits means that, regardless of how beautifully architected your application is, its inputs and configuration are probably going to be changing all the time. The dizzying number of possible configuration combinations combined with the frequency with which we need to cycle through them makes ensuring consistent output quality one of our core engineering challenges.
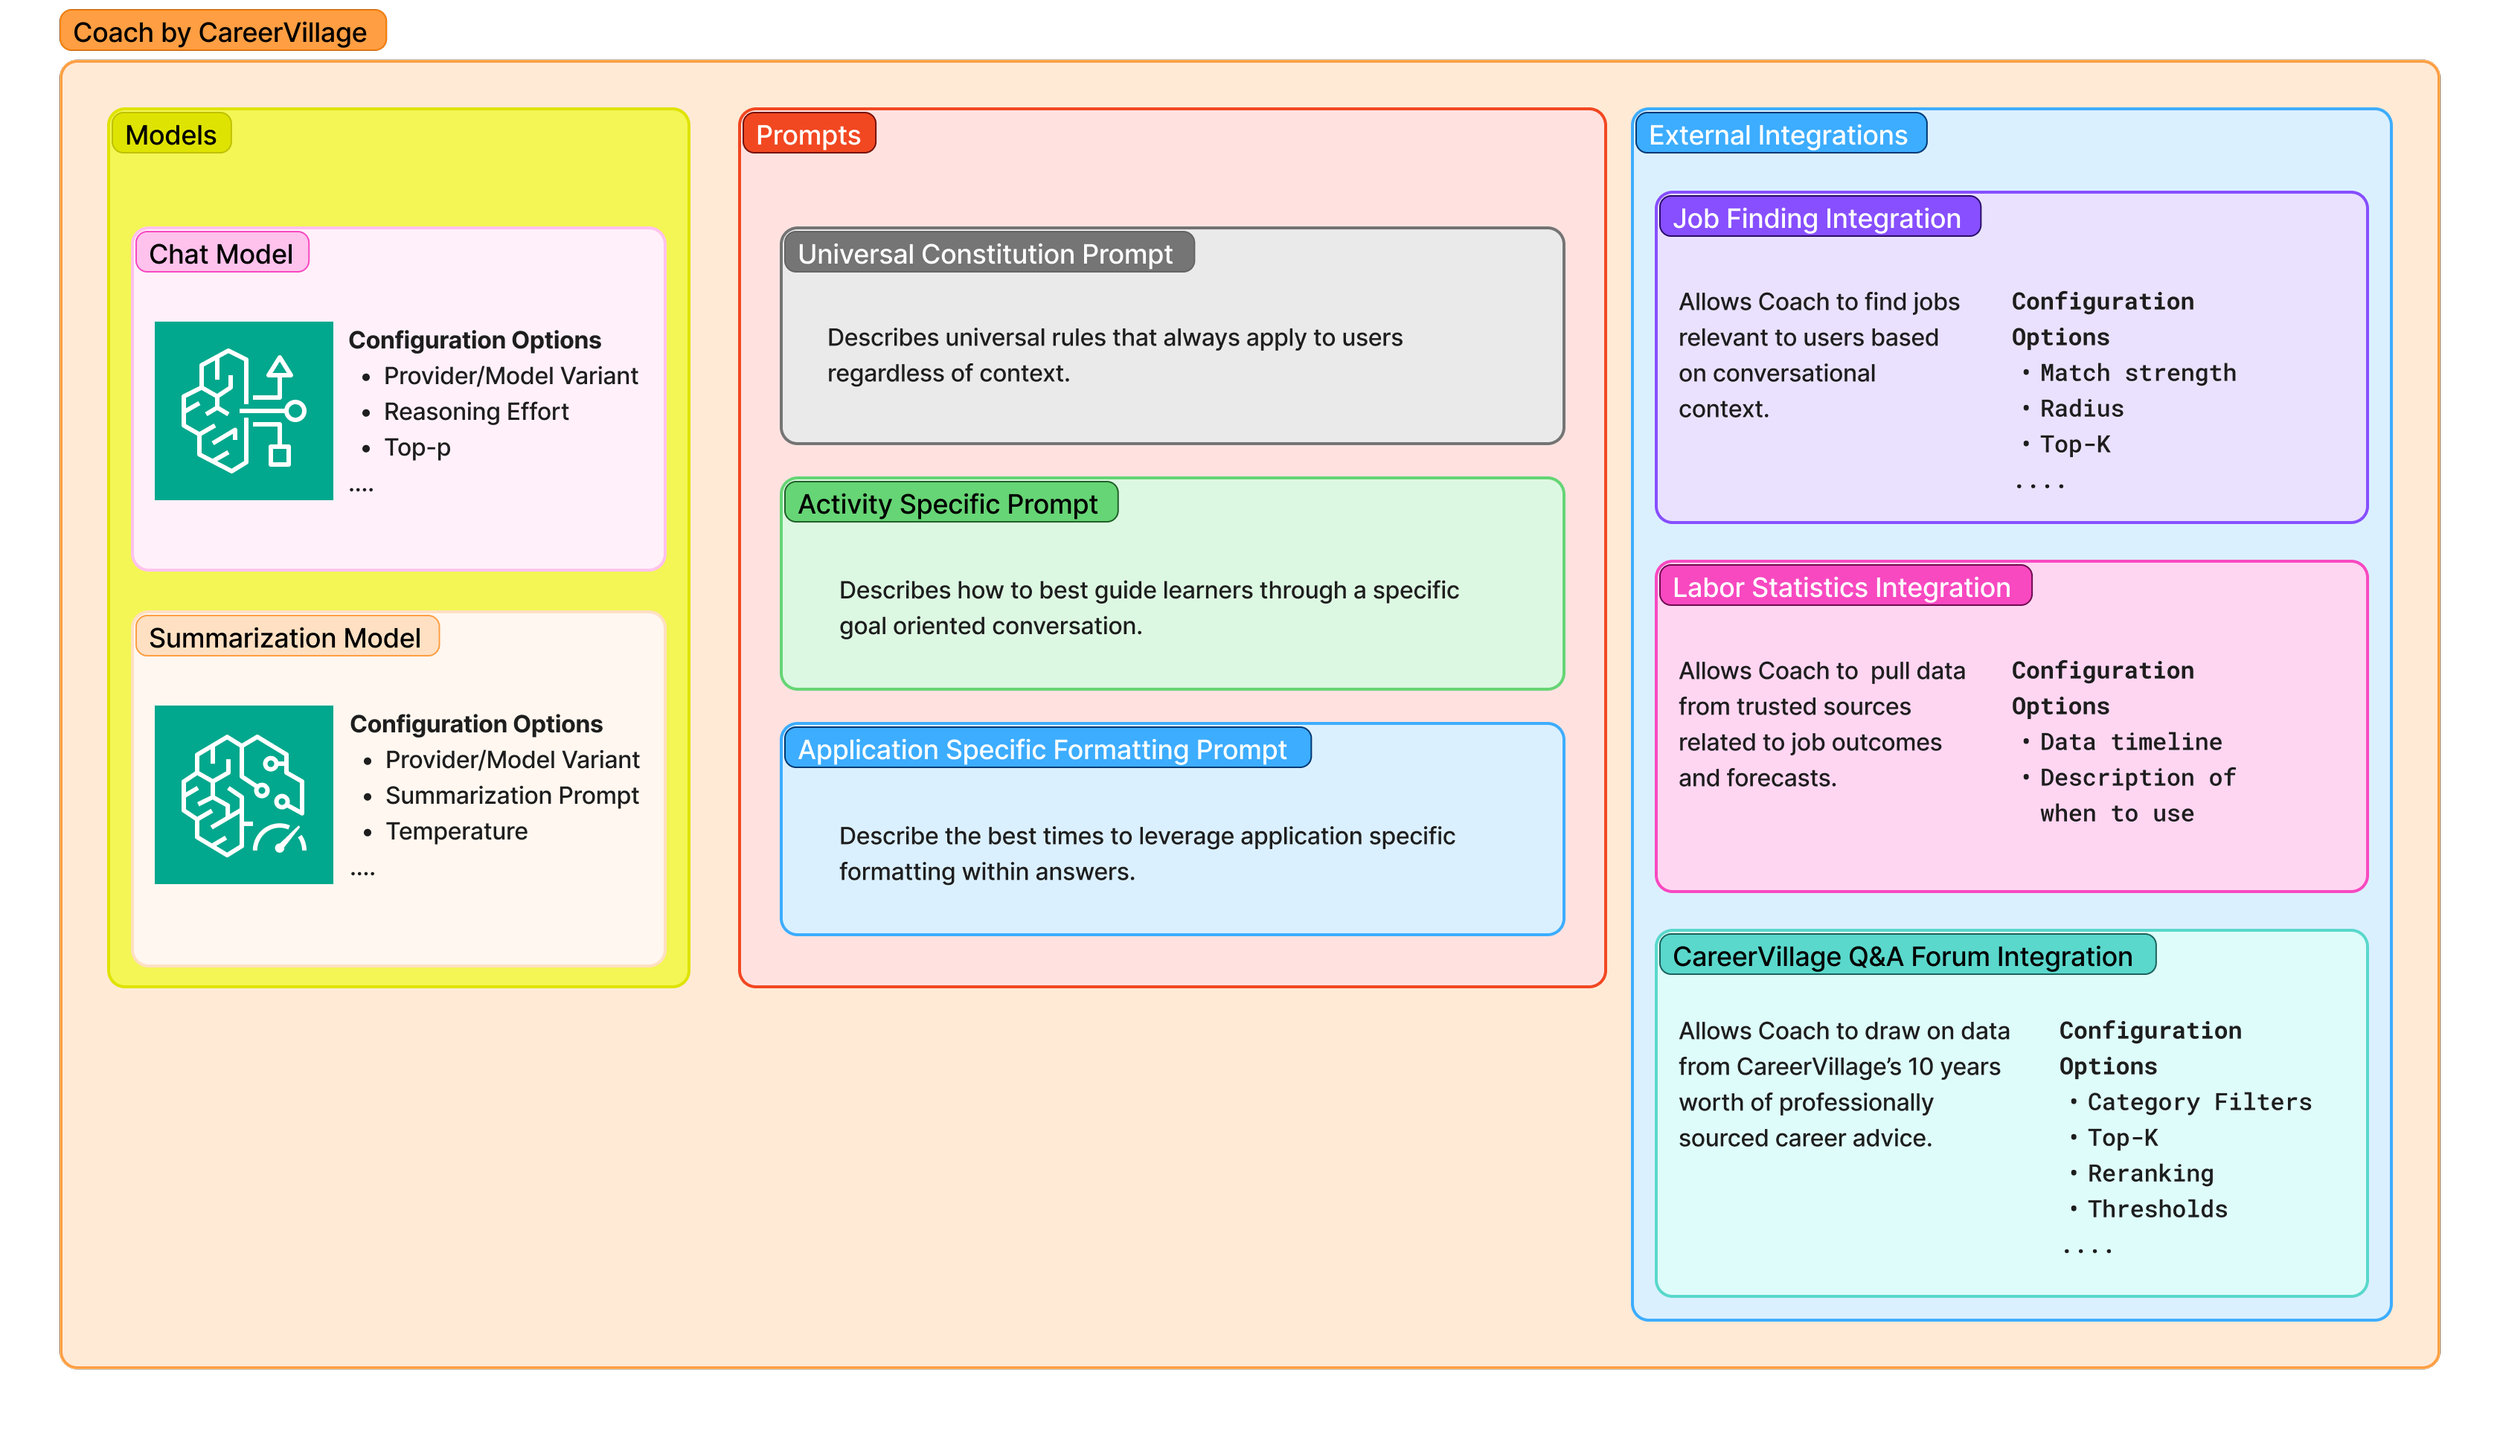
Coach is made up of many different components, many of which have distinct parameters that get updated during experimentation. The image above is conceptual and not a strict 1:1 representation of Coach’s architecture, but hopefully illustrates how many different configuration levers exist in a system like Coach.
A historical detour: the evolution of NLP tasks and the metrics used to evaluate them
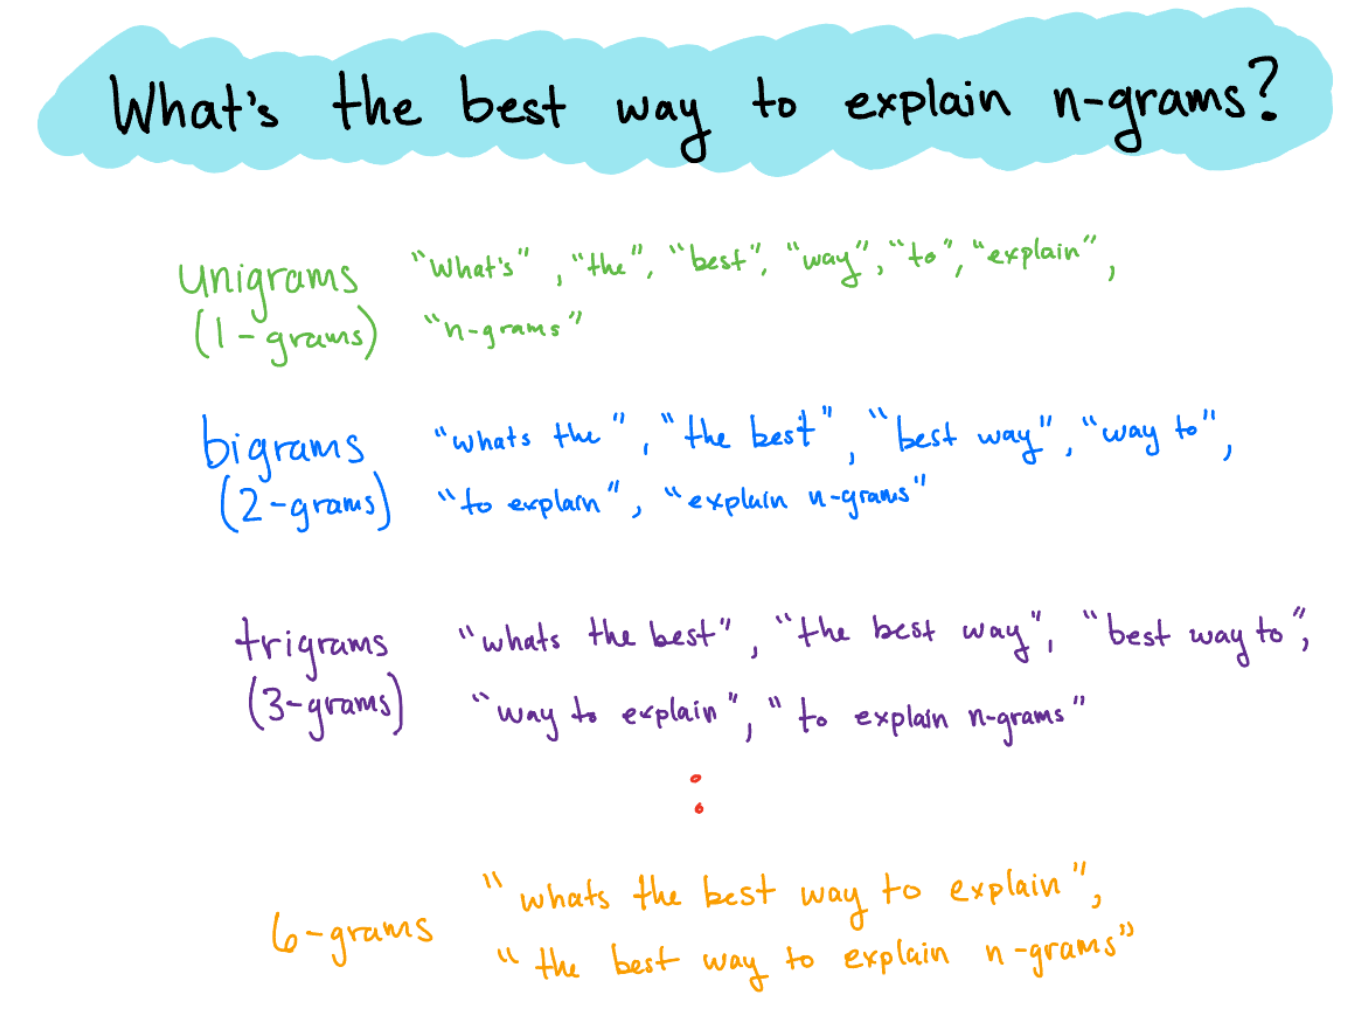
N-grams are a language processing technique that makes sentences easier for computers to model and analyze. They do this by breaking text into contiguous sequences of n words, which makes it computationally efficient to detect repeating patterns across large bodies of text.
Generative AI has laid the groundwork for applications like Coach, where each input from an end user has a nearly infinite number of responses or outputs that could be considered high quality. Systems like these don’t neatly map to the previously dominant NLP tasks like translation and speech recognition, and as such, these new systems require more dynamic evaluative approaches to match the dynamic nature of their potential outputs. Over the last few years, LLM-as-a-Judge has gained relatively wide adoption across industry practitioners as a framework for assessing quality of LLM driven tasks. LLM-as-a-Judge is exactly what it sounds like: using an LLM to judge the outputs of another LLM. While this might sound a bit ridiculous at a glance, there are a number of implementation considerations that can make it work surprisingly well for specific situations. In the sections to follow, we’ll walk through the decisions we made while building our internal framework and highlight what came together well for us while using LLM-as-a-Judge to evaluate Coach’s output.
LLM-as-a-Judge for conversational evaluation: what worked for us
In an ideal world,every AI-based product would have a willing army of human annotators ready to review the generated content and grade it on the dimensions most important to the quality of the product. Your gold-standard human annotator corps would be especially valuable in evaluating dimensions like tone, complexity, and correctness since these measures are subjective and would likely elude being effectively determined by traditional programs like unit tests. For those of us who don’t have a department of human annotators at the ready, LLM-as-a-Judge is our next best bet. At a high-level the LLM-as-a-Judge approach is essentially writing a prompt describing how you want an LLM to evaluate a piece of content, inserting the content to be evaluated, and then defining the potential outputs.
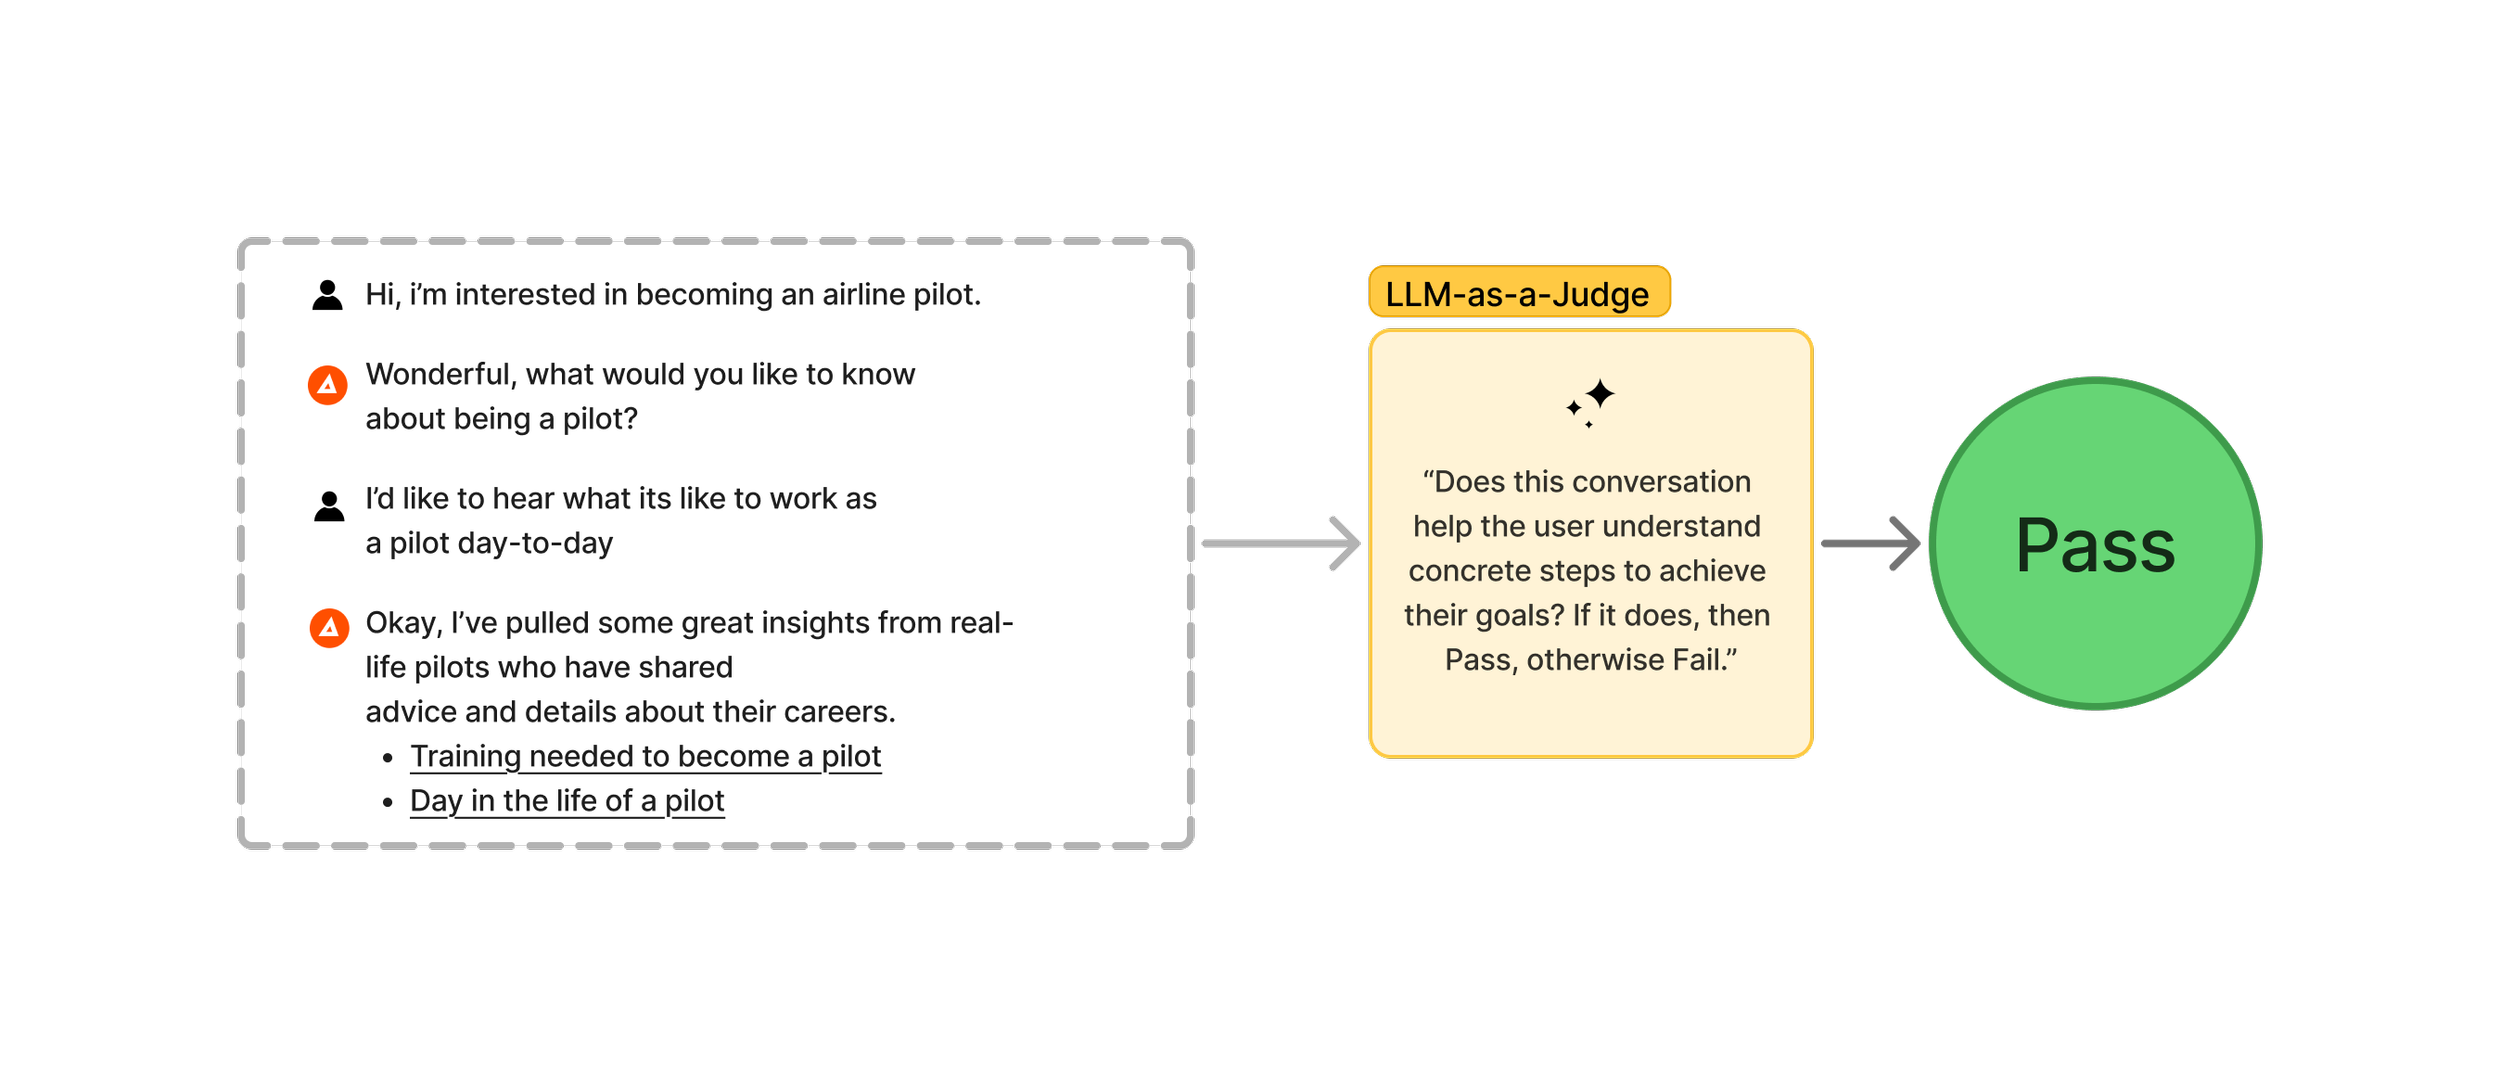
LLM-as-a-Judge is a technique that can be used to scale up evaluation of conversations by using large language models.
Model selection & ensembles
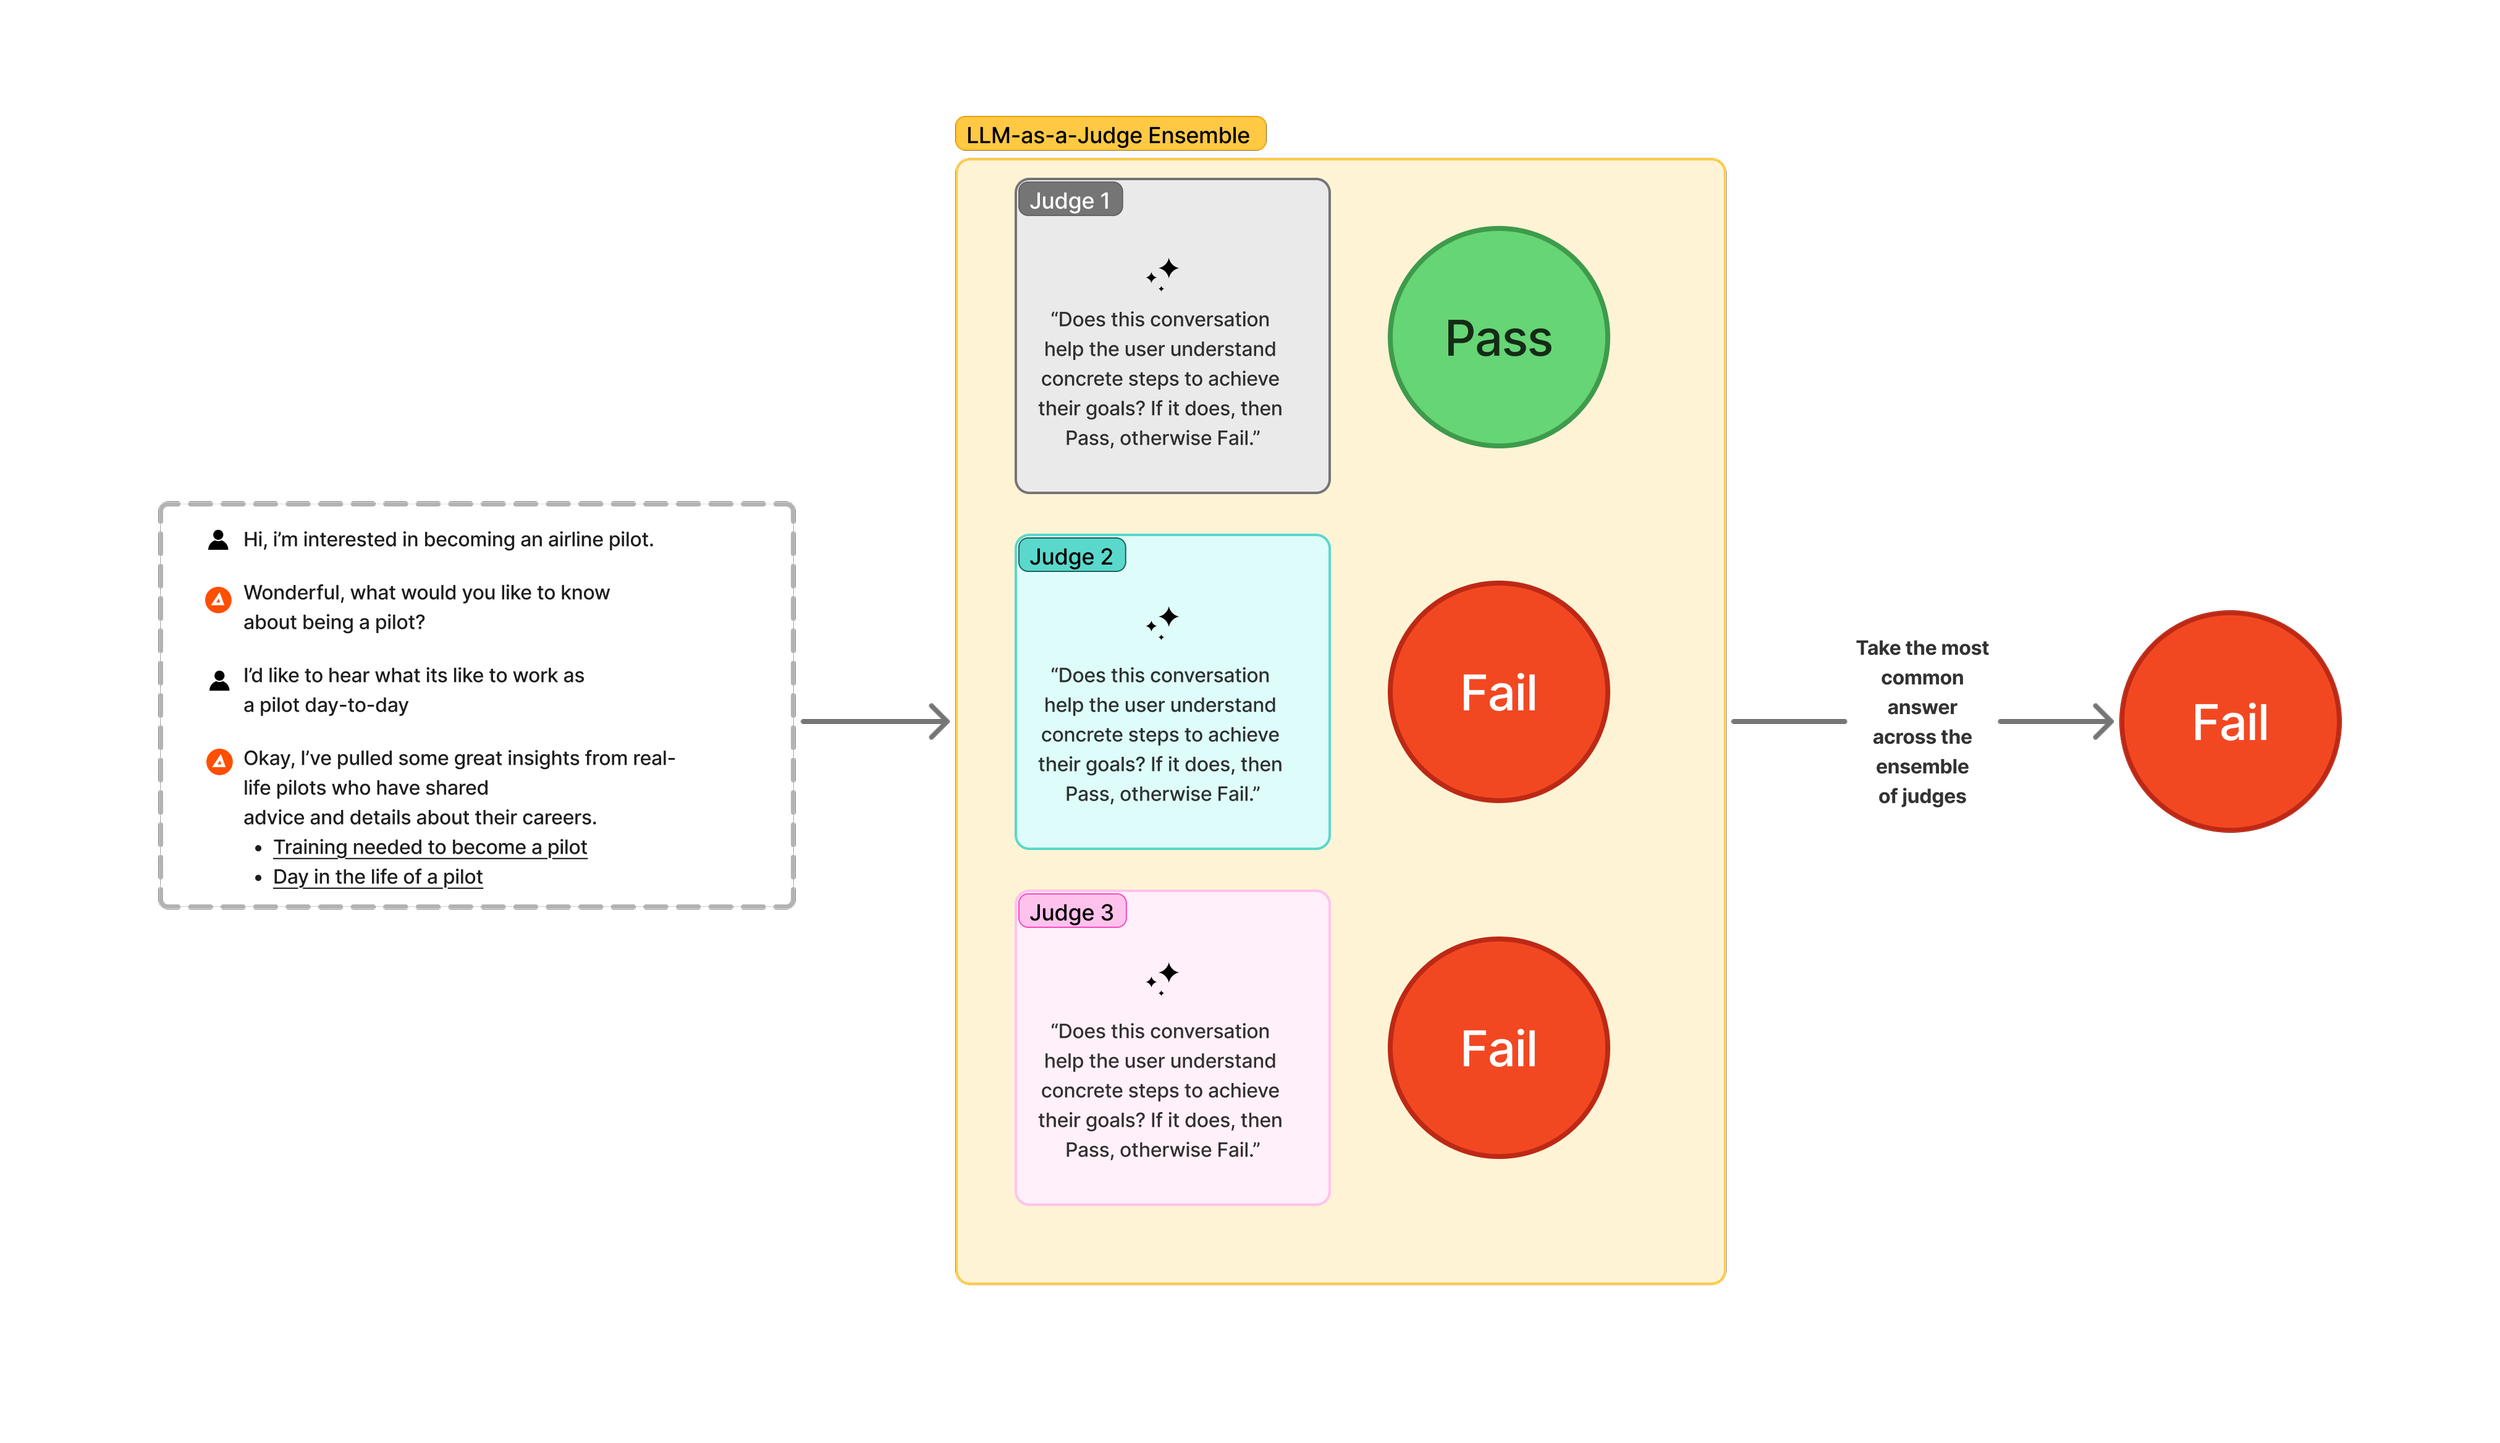
LLM-as-a-Judge ensemble is an extension of the LLM-as-a-Judge technique that makes a final determination based on an aggregated answer from multiple judges.
Evaluation scoring
Putting it all together
In the following sections we will discuss how we brought each of the previously discussed components together to build Coach’s evaluation system. We’ll detail how each of these techniques come together to guard the application against quality deterioration during our experiments with different prompts, models, and other configuration levers.
Creating multi-turn conversational inputs
Despite having multiple years’ worth of conversational data generated from real users seeking career advice, looking for help choosing majors, and preparing for jobs, we couldn’t actually use this data directly. While the existing conversations were critical in helping us understand our user types, conversational failure modes, and strength areas, we had no way of using those exact conversations to re-run against different models or different prompts or different configuration options. Consider the following hypothetical chat transcript:
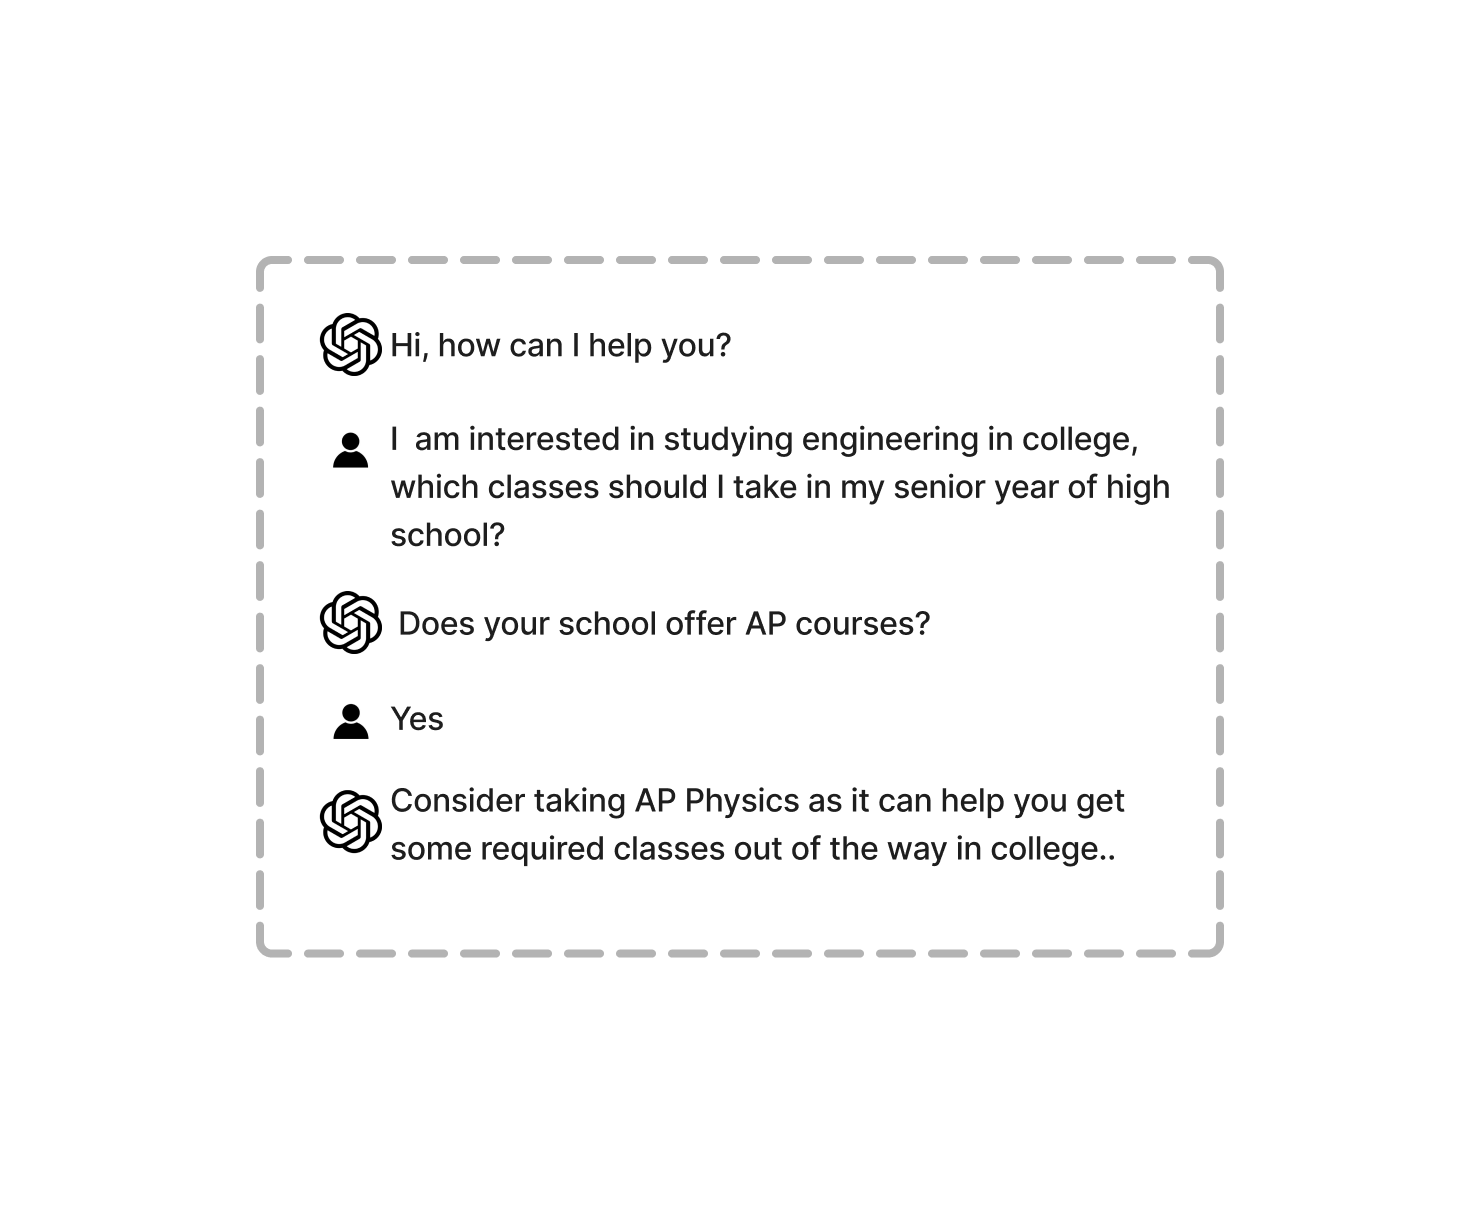
If we wanted to use this data to re-run the same conversation with a new model, we could consider the user’s messages as the hard-coded inputs for recreating the conversation. Let’s say, as a hypothetical, that the original transcript was generated using OpenAI’s GPT-5.1, and to see how Anthropic’s Haiku 4 would do in the same situation, we used the user’s exact same inputs to attempt to simulate the conversation.
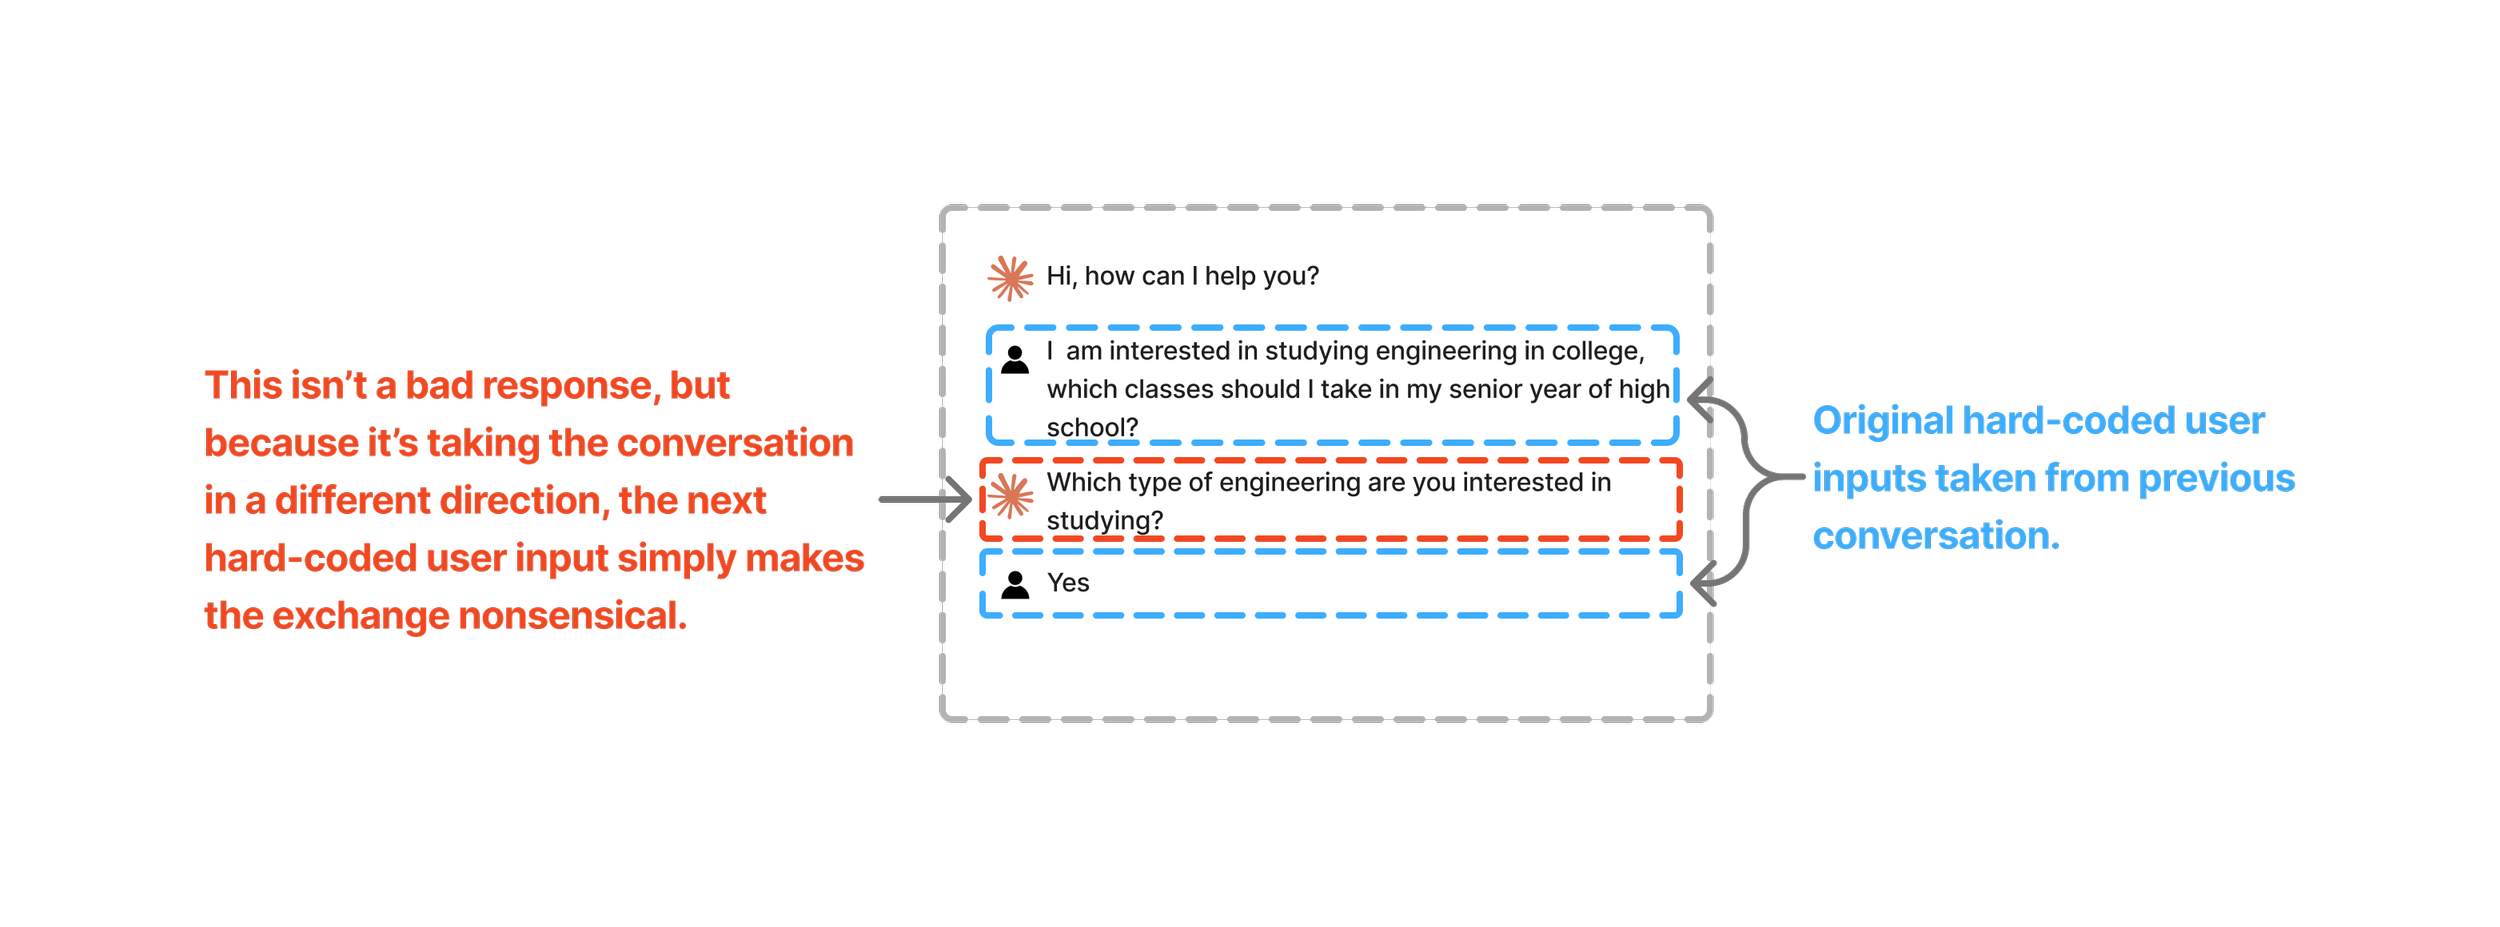
While this example is a bit contrived, it hopefully illustrates the trouble with trying to use historical conversational data as a direct input for testing new models, configurations, or prompts in your application. In this case, the non-deterministic nature of LLMs forces us to consider more creative approaches for generating representative conversations for testing.
Instead of feeding user inputs directly into our systems with new configurations, we decided to leverage our historical conversation data indirectly. Our solution was to create representative user personas that attempted to capture the feelings, attitudes, and contexts present across our distribution of users.
Our work developing these personas consisted of reviewing conversation transcripts across users with a spectrum of experiences within our application; those with varying activity levels, differing survey responses, countries of origin, etc. Each representative user persona we created then served as an input for an LLM prompted to simulate how a user with that particular profile would respond to Coach. In essence, we pivoted to creating synthetic data that was rooted in the historical behavior of our users. By running each of these synthetic users across the combination of configuration options we wanted to test, we were able to generate a new set of conversations that we could then feed into our ensemble-based evaluation system.
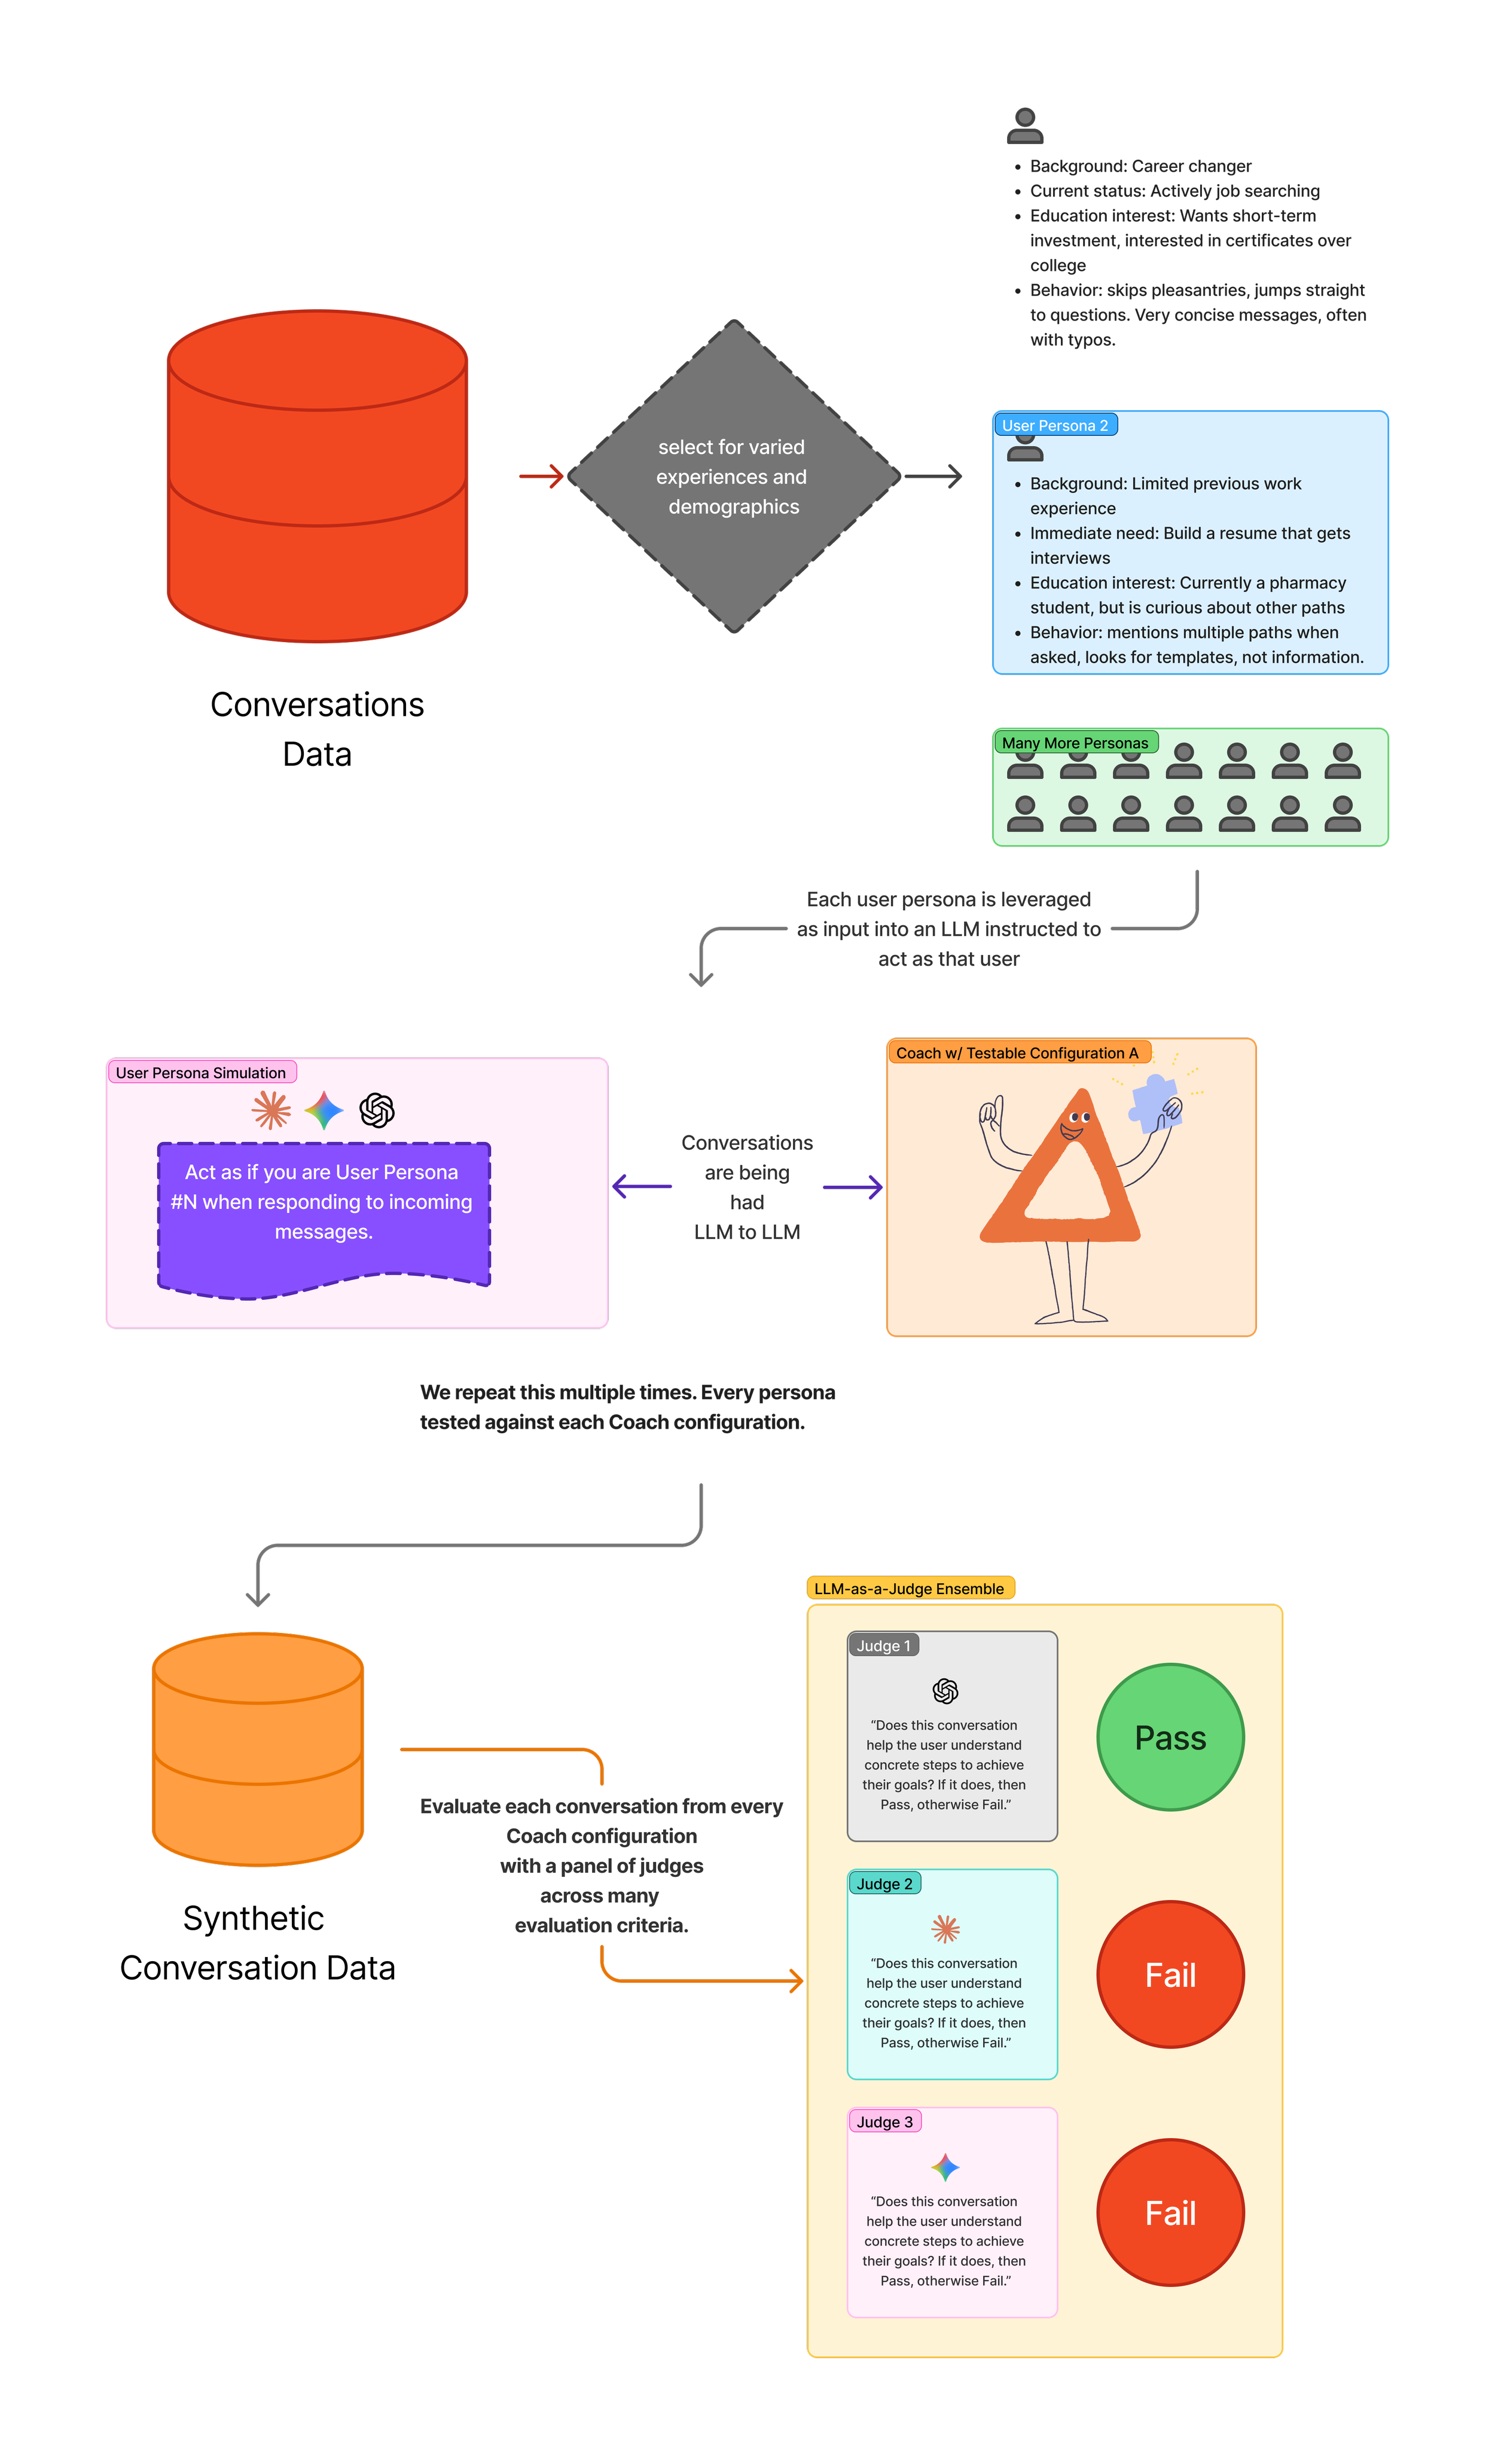
Our end-to-end evaluation system for Coach for validating quality of outputs during experimentation.
Supplementing with application-specific deterministic tests
Everything previously discussed outlines how we test the quality of conversational content. Which is admittedly a very significant portion of what we care about. However, there are smaller application-specific considerations for Coach that don’t fall within the scope of “conversation quality” and, as such, are not handled well by the LLM-as-a-Judge approach. In order to create a robust evaluation system that accurately measured our end-to-end functionality, we needed to take other factors into consideration. In this section, we’ll walk through two specific such considerations. While these considerations are specific to how we’ve built Coach, we’re exploring them here to share examples of how LLM-as-a-Judge often isn’t enough and should be supplemented with identified application-specific failure modes.
Citation URL hallucination
For most conversations that Coach engages in, we include instructions that tell it to include citation links to relevant sources wherever possible. In most cases, this is done with tool-based retrieval for specific URLs. However, in some testing instances, we’ve seen models fail to call a tool and return a legitimate URL that contains relevant data. In other cases, we’ve seen models fail to call a tool and then hallucinate a realistic-looking URL that actually leads to nowhere. As a simple, deterministic test, we created a script that uses regular expressions to detect links in chat responses and then pings them to validate that they are at minimum real URLs that return 2xx status codes. Simple tests like these are cheap to write, deterministic, and can help detect how different prompts, models, or configurations might reintroduce known failure modes into your system.
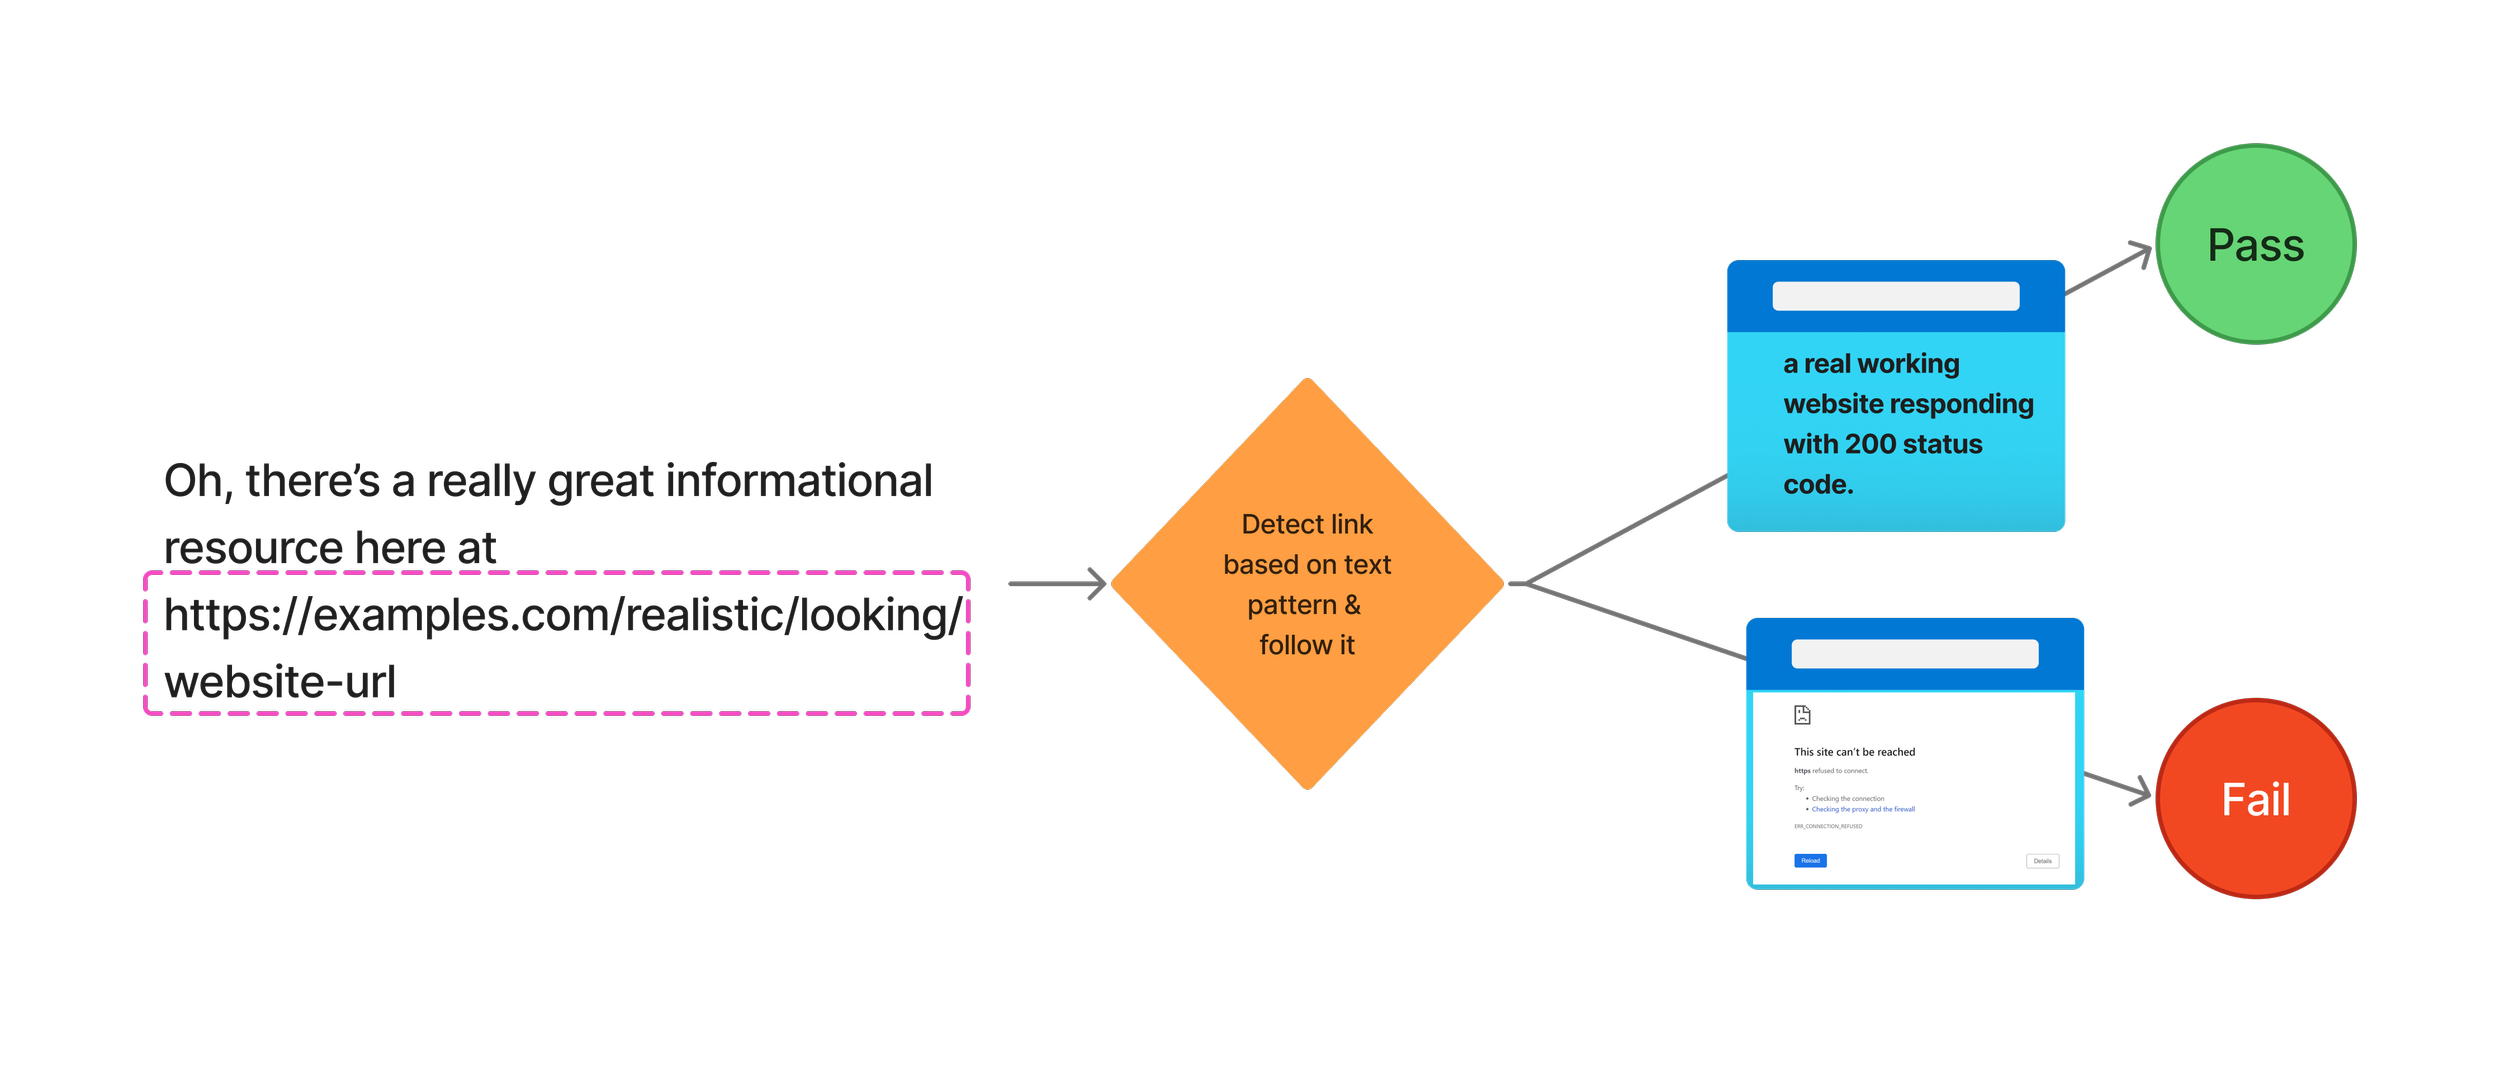
Whenever Coach produces links, they always look realistic. We use a test like this to make sure that they lead to real and active websites. Early on in development, URLs were one of the most common places that we found hallucinations occuring.
Text schema-based rendering
Another application-specific failure mode we built tests for is our in-chat interactive rendering. For certain activities, Coach often creates interactive elements that users can click on directly to trigger an action or see more detailed information. One example would be in our job exploration activity; we have integrations with a number of job feeds that allow us to surface relevant job postings mid-conversation (it's really cool). We do this by prompting Coach to represent job postings with a very specific text format (sometimes referred to as a schema). When our front-end sees this very specific combination of text, it knows to show a clickable job posting card instead of the text itself. But, if Coach gets the text format incorrect, then jobs simply don’t show up, or worse, the ill-formatted text schema will show up directly in the chat, which would be an unpleasant and confusing experience for our users. So, to prevent new models or other configuration changes from introducing these types of bugs, we created a regular expression based test as part of our suite that validates that the text format matches the expected schema.
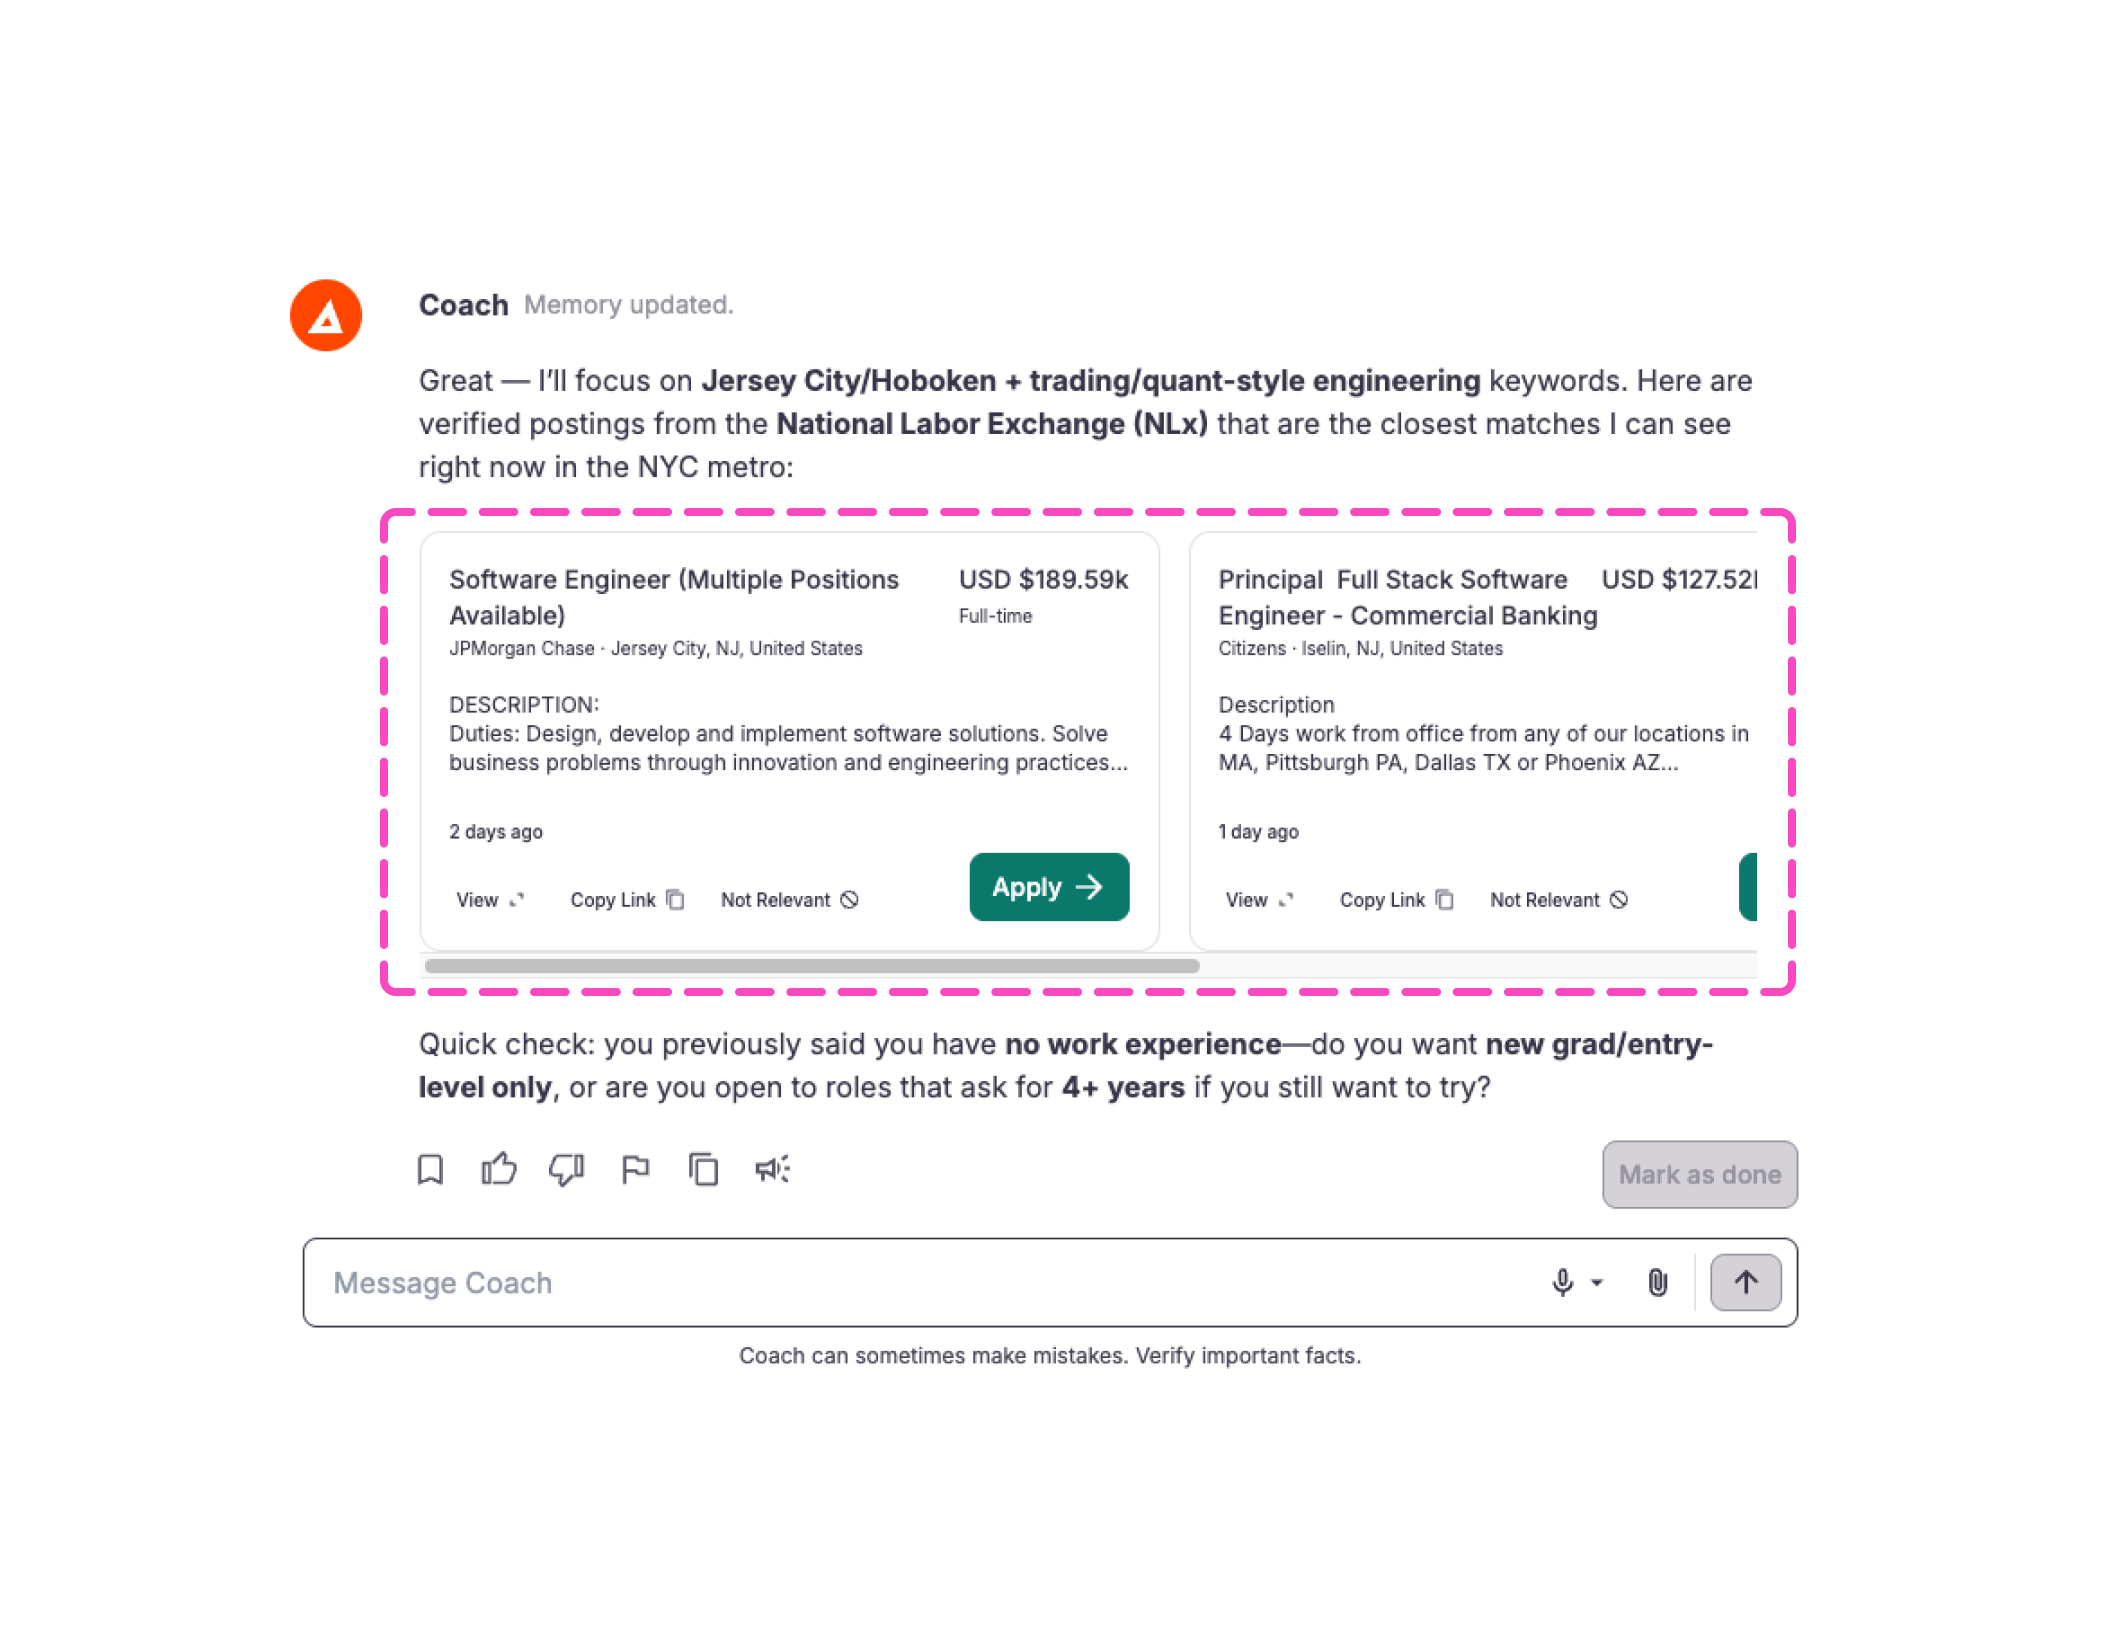
The job cards highlighted in pink are rendered based on a very specific text schema produced directly by an LLM. So whenever we change models or prompts, we run tests that validate that Coach still consistently produces text that complies with our schema.
Validating with human annotators & beyond
As a last step, we want to make sure that all the fun techniques we’ve been dreaming up and working on actually approximate what we set out to mimic– human judgment. To check our end results, we took a random sample of generated conversations and judged them on the same criteria as our LLM counterparts. We then compared our human-generated evaluation scores with those output by our ensemble of judges. In the event that we had disagreement in the samples, we would take a closer look at the conversation and figure out if there were additional adjustments to the prompt or criteria that needed to be made.
Final output
When it was all said and done, we ended up with something like this. While these numbers and criteria are not exactly what we used internally, the idea is the same. For all the synthetic conversations generated from the derived user personas, figure out how well each configuration (in this case just the model choice in the first column) performs across the dimensions that matter most for your use case!
Future optimizations
We believe that the approach outlined in this article represents a significant step forward in our ability to fulfill our goal of building the most trusted AI-powered career coach. Our system gives us the ability to explore the vast array of configuration and model options without fear of quality loss; allowing us to experiment as the technical landscape continues to evolve rapidly.
From the blog
Expanding Coach: A new partnership with NextLadder Ventures
The largest investment in CareerVillage to date will put career guidance within reach of more young people.
How Athens State Is Opening Doors to Career Coaching and AI for Adult Learners
Like most universities, Athens State has always had a Career Services office with an open-door policy. The challenge, however, is that career development is...
Coach Anywhere: Career Coaching, One Text Away
Introducing Coach Anywhere. Now learners can connect with Coach directly from their phones via text.